A follow-up to introducing Polyglot: I benchmarked it against three other coding agents on open-weight models, to check whether my core assumption was even true.
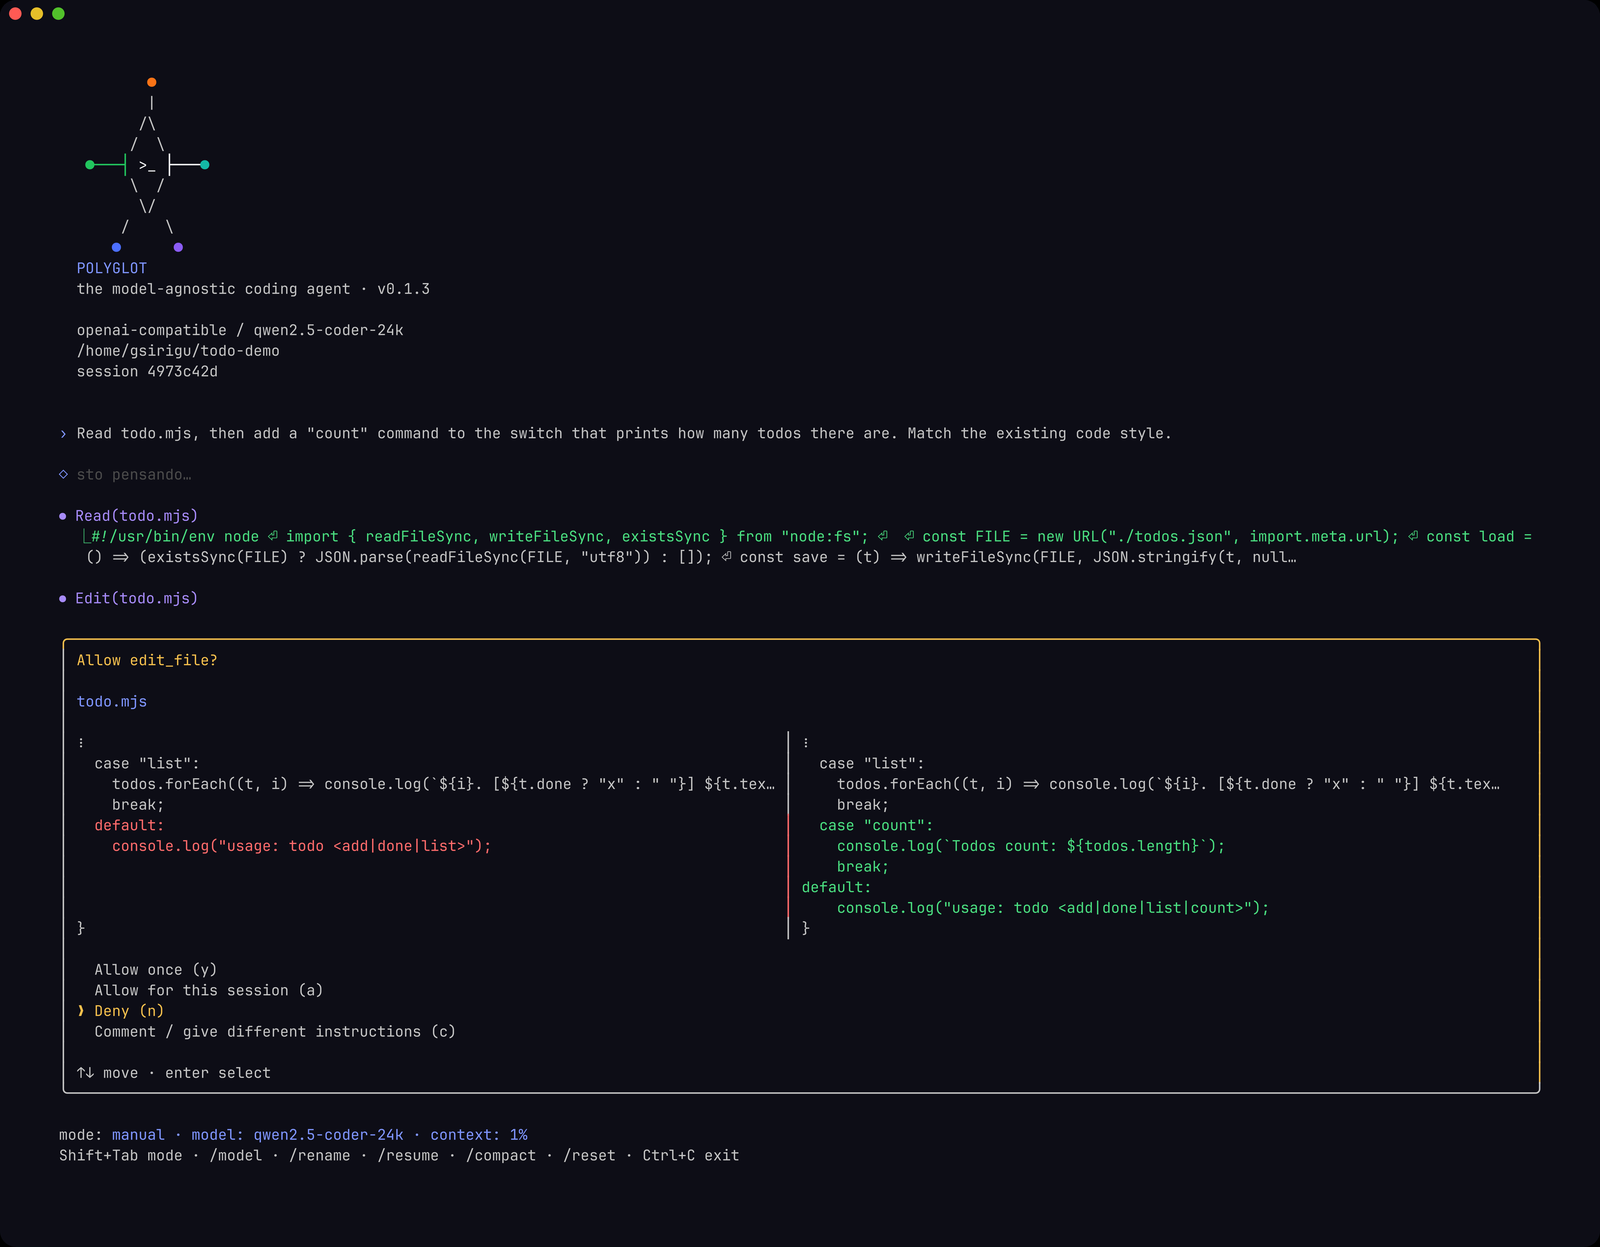
A coding-agent CLI that behaves the same whether the model is Claude, GPT, or an open-weight model running locally - because it treats tool calls as a text-parsing problem, not an API contract.
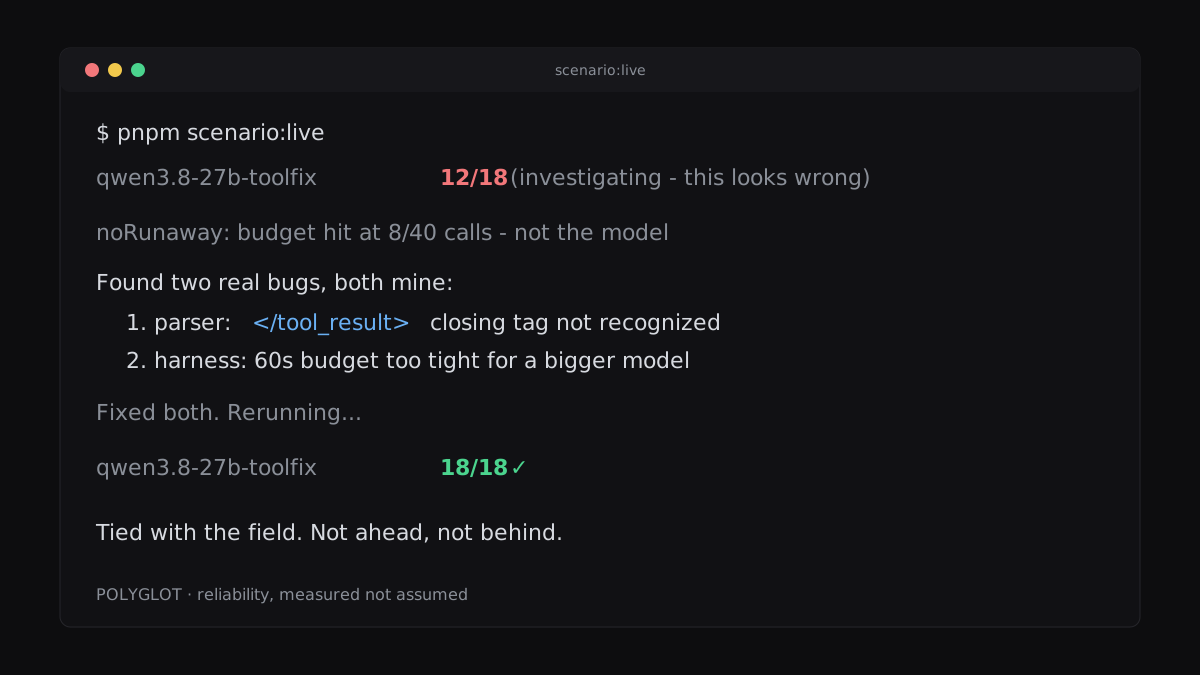
A week of real pushback on the Polyglot benchmark forced me to actually check my own work - including on myself.